How a run works
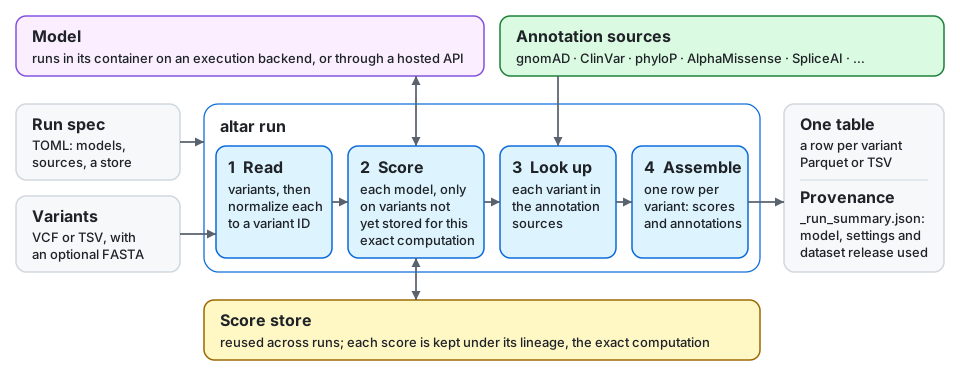
altar run reads a run spec, scores your variants with each model, looks each variant up in each annotation
source, and writes one table with a row per variant. The run spec is a TOML or JSON file that names the variants,
the models, the annotation sources, where model tasks run and where scores are kept. Run
spec lists its keys.
Checks before any variant is read
The run first checks everything it can without reading the cohort:
- each
typein the spec names a model, source, backend or store that is installed; - each model's settings are valid, and each model and source can serve the genome build in
[run] genome_build; - each annotation source opens, which can mean reaching a published copy over the network;
- a model that runs in containers has a
[backend], and the filesaltar preparewrites for it are in place; - each annotation column a model's prioritization rule reads comes from a source in the spec.
A failed check stops the run before it reads a variant or starts a task. altar run --validate makes the same
checks and stops there.
Variants are read and normalized
The run reads the VCF or variant TSV that [variants] path names. A multi-allelic VCF record becomes one variant per
alternate allele. Alleles that name no sequence, such as <DEL>, are dropped and counted.
Each variant gets a variant ID, chr:pos:ref:alt, and is normalized: trimmed, and left-aligned when [variants]
reference_fasta gives a reference genome. Two rows that normalize to the same variant become one. The run writes
the normalized cohort to <work_dir>/variants/<job_id>.candidates.tsv. Variant identity and
normalization gives the rules.
Each model scores only what is missing
Models run one after another, in the order of the spec. For each model, the run:
- Sets aside the variants the model cannot score, such as an indel for a model that scores SNVs only, or a variant whose REF differs from the reference genome. Their score columns stay empty.
- Skips the variants the score store already holds for this model and these settings. Score reuse and provenance says when a stored score counts.
- Splits the remaining variants into batches of up to 10,000, or
max_variants_per_batch. - Asks the model's binding for a plan for each batch, runs the plan, and stores the results.
Score variants with a model reads the line the run prints for each model, which counts each of these groups.
A plan describes the work
A plan is the binding's description of the work for one batch. It takes one of two forms:
- Container tasks. A task is one unit of work that runs on its own: a container image, the command to run, the files it reads and writes, and the compute it needs, such as one GPU. LegNet scores a batch in one task. ChromBPNet runs one task per fold, then one task that combines the folds.
- A call made from the
altarprocess. AlphaGenome's plan is a request to its hosted API, so it needs no container.
A backend runs the tasks
A task names no machine. The execution backend in [backend] decides where it runs: local runs it with Docker
on this machine, kubernetes on a cluster, and modal on Modal. The last two are Preview. One plan runs on any
of them. Before a task's command runs, its input files are copied into place, and each input that has a SHA-256
digest is checked against it. Run tasks on a GPU or a cluster sets up each backend.
Outputs are checked and stored
When a batch's tasks finish, the binding reads their output files. Altar checks each row against the score columns the binding declares. A row for a variant the batch did not include, or for one the model cannot score, is an error. Altar then stores the batch's artifacts, then its detail tables, then its score rows. A variant counts as scored once its score row is stored.
A batch that fails stops the run. The batches before it are already stored, so running the same spec again scores only the variants that are left.
The export assembles one row per variant
After the last model, the run reads the cohort back through the score store. For each variant it:
- reads each model's scores for the settings in the spec;
- looks the variant up in every annotation source;
- evaluates each model's and source's prioritization rule.
It writes one row per variant, sorted by variant ID, as Parquet or gzipped TSV. Every variant of the cohort has a
row, including one a model set aside or a source has no record of, unless [export] prioritized_only keeps only
the prioritized rows. Beside the table the run writes a summary of what it did. The table carries a provenance
record of the model settings and dataset releases each column came from. Read a run's results
reads all three.
Annotations are not stored between runs. Each run looks them up again, so adding a source or reading a new release runs no model.
Runs without models
A spec without models only annotates. It needs no [backend] and no [store]: the export then reads through a
store held in memory, and the run writes no store file and creates no cache. Annotate variants with
evidence walks through one.
Why the pieces are separate
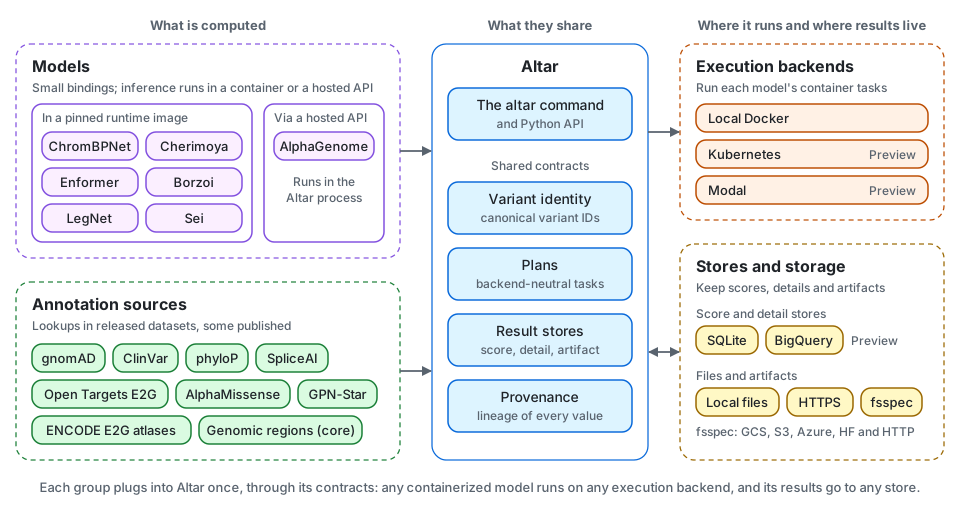
The spec chooses each part of a run on its own: the models, the annotation sources, the backend and the stores. A model's plan names no backend, and a backend runs any model's tasks. A store keeps any model's scores. A model that runs in containers therefore runs on local Docker, Kubernetes or Modal, and any model's scores go to SQLite or BigQuery, with no code written for that pairing.
Models and datasets come in separate packages, called bindings, so you install only the ones you use. A model's framework, such as TensorFlow or PyTorch, is inside its container image, not in your Python environment. Models, sources and bindings describes what each provides.
Next
- Models, sources and bindings describes the parts a run is built from.
- Where results live describes the score store, detail tables, artifacts and the export.